The Data-Labelling Bottleneck — Why India’s AI Ad Tools Still Depend on Human Annotators

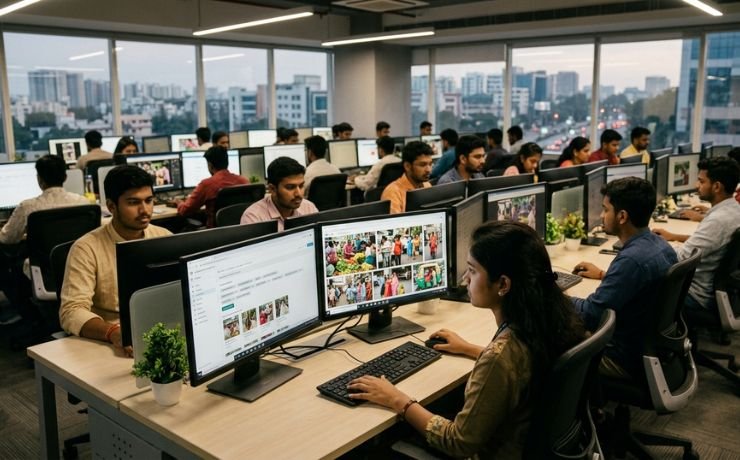
Every AI-powered ad tool pitched to an Indian marketer arrives with the same promise: give it a brief, and it will return creative, targeting and optimisation at a speed no agency team can match. The demos are slick and the dashboards are tidy. What rarely makes it into the pitch deck is the workforce behind the curtain, thousands of people in Bengaluru, Hyderabad, Kolkata, Jaipur and smaller towns, drawing boxes around objects, tagging sentiment, correcting transcripts and deciding whether a line written in Hinglish is sarcastic or sincere.
That workforce is the quiet bottleneck of India’s AI advertising boom. The models get the headlines, the compute gets the investment, and the data gets treated as a commodity. Yet for any tool expected to understand how a Tamil-speaking shopper in Coimbatore differs from a Hindi-speaking one in Lucknow, the quality of human-labelled data remains the factor that separates a useful product from an expensive disappointment.
The invisible layer beneath the interface
Machine learning, for all its sophistication, begins with a simple act of teaching. A model learns to recognise a product shot, flag an unsafe video or predict which creative will hold attention because someone, somewhere, first showed it thousands of examples marked correct and incorrect. That marking is data annotation, and it is still overwhelmingly done by people.
In an advertising context, the range of tasks is wider than most buyers appreciate. Annotators classify content for brand safety, deciding whether an article about a political rally or a film controversy is a suitable neighbour for a premium advertiser. They tag creative assets by theme, tone, colour palette and format so that optimisation engines can learn what works. They transcribe and translate video and audio so that contextual targeting has something to read. And increasingly, they rank and rewrite the outputs of generative models, the preference-based feedback that teaches a system what a good headline or a believable voiceover actually sounds like.
None of this work is glamorous, and almost none of it is visible to the marketer who logs into a platform and sees a clean “AI-optimised” label. But every one of those labels rests on a human judgement made at some earlier point in the chain.
Why India is harder than the demo suggests
Much of the world’s leading AI advertising technology was built first for English-speaking markets, where training data is abundant and cultural signals are comparatively well mapped. India offers no such luxury. The country has twenty-two scheduled languages and hundreds of dialects, and the way people actually write online bears little resemblance to textbook grammar. A single social media comment can move between English, Hindi and a regional language within one sentence, written in Roman script, with slang that changes from one city to the next.
For a sentiment model, this is a minefield. A phrase that reads as praise in one region can carry a mocking undertone in another. A festival reference that signals celebration in the north may mean little in the south. Humour, irony and politeness conventions vary so widely that automated systems trained largely on Western data routinely misread them. The result, for advertisers, is not dramatic failure but quiet leakage: campaigns that target the wrong moments, brand-safety filters that block harmless content, and creative recommendations that feel faintly off.
Closing that gap requires labelled data that reflects Indian reality, and that data cannot be conjured from scraped English text. It has to be produced by people who understand the language, the region and the context. This is precisely why the annotator, far from being made obsolete by progress, has become more valuable as tools push deeper into vernacular markets.
Where the bottleneck actually bites
The constraint shows up in several places at once. The first is scarcity of quality. Plenty of vendors can supply annotators in volume, but far fewer can supply people with the linguistic depth and domain familiarity to label advertising data well. Tagging a clip of a regional cricket telecast for brand suitability is a different skill from drawing bounding boxes around traffic signs, and the pool of workers who can do the former reliably is smaller than the industry tends to admit.
The second is consistency. Two annotators reading the same ambiguous caption can reach different conclusions, and when thousands of such calls feed a single model, small disagreements compound into noisy behaviour. Mature teams invest heavily in guidelines, calibration sessions and layered review, which is slow and expensive. Teams that skip those steps tend to discover the cost later, when a model that looked impressive in testing behaves erratically in a live campaign.
The third is speed. Advertising moves with the news cycle, with cricket seasons, festival calendars and election periods. Language shifts quickly too, as new slang, memes and product names enter circulation. Labelled datasets age faster than most buyers expect, which means annotation is not a one-time project but a continuing operational expense. A model that understood last year’s conversation may stumble on this year’s.
The economics nobody likes to discuss
India’s reputation as a base for data work was built on cost advantage, and the commercial logic still drives a large part of the market. Global technology companies and their suppliers route annotation work to Indian vendors because skilled labour is available at a fraction of Western rates. That arrangement has created real employment, including opportunities in smaller cities and for people who might otherwise have limited access to digital work. A handful of Indian ventures, such as Karya, have gone further and built models explicitly designed to channel better pay to rural workers, treating data work as a livelihood rather than a race to the bottom.
But the cost-first approach carries a tension that is becoming harder to ignore. When pricing pressure pushes vendors to maximise throughput, quality is often the first casualty, and so is the wellbeing of the people doing the work. Annotators reviewing brand-safety content can be exposed to disturbing material for long stretches. Pay can be thin, contracts short and career paths unclear. For an industry that frequently talks about responsible AI, the labour conditions underneath it deserve at least as much scrutiny as the algorithms on top.
There is also a commercial argument, not only an ethical one. Fatigued, underpaid and poorly trained annotators produce weaker labels, and weaker labels produce weaker products. Brands that care about the reliability of the tools they buy have a direct interest in how that data was made.
Can automation close the gap?
The obvious response is to use AI to label data for AI, and the industry is already moving that way. Model-assisted annotation lets a system pre-label content so that humans only verify or correct it, cutting the time per item considerably. Synthetic data, generated by models to fill gaps in training sets, is attracting serious attention, particularly for languages where real examples are scarce.
These techniques are genuinely useful, but they do not remove the human from the loop so much as change where the human sits. A model that pre-labels content inherits its own blind spots, and without careful review those errors can be reinforced rather than corrected. Synthetic data raises a related problem: if a model generates the examples used to train its successor, any bias or misunderstanding about Indian languages and culture can be amplified with each cycle. The people best placed to catch such drift are the same annotators and reviewers the technology was supposed to replace.
What emerges, then, is a more skilled and more selective role. Routine labelling will be increasingly automated, while judgement-heavy work, such as edge cases, cultural nuance, safety calls and evaluation of generative output, will stay with people. The bottleneck does not disappear. It narrows, and it moves up the value chain.
Public efforts and the policy backdrop
India’s institutions have recognised the language problem, even if the solutions are still maturing. Government-backed initiatives such as Bhashini aim to build open language resources and translation capabilities across Indian languages, while research groups like AI4Bharat have published datasets and models designed for the country’s linguistic diversity. For advertisers and platform builders, these efforts offer a useful foundation, though they are a starting point rather than a finished answer for the commercial nuances of marketing.
Regulation is also beginning to shape the conversation. The Digital Personal Data Protection Act, 2023, places obligations on how personal data is collected and handled, and any annotation pipeline that touches user comments, voice recordings or images has to reckon with those duties. Questions about consent, retention and who has access to raw data are no longer abstract for vendors. At the same time, scrutiny of AI-generated content and how it is disclosed to audiences is growing, which will only increase the demand for human review before such content reaches the public.
What brands and agencies should be asking
For the marketer or agency leader evaluating an AI tool, the data question is rarely on the checklist, yet it may be the most revealing one. A vendor that can speak confidently about where its training data came from, how it is labelled and how often it is refreshed is usually a vendor that understands its own product. One that deflects is signalling something too.
A few lines of inquiry are worth pursuing. Was the model trained or tuned on Indian-language data, and which languages and dialects does that actually cover? How are annotators selected, trained and reviewed, and what steps exist to measure agreement between them? How does the vendor handle brand-safety edge cases in regional content? What is the process for updating the model as language and culture shift? And how are the people doing the labelling treated and compensated, given that this affects both quality and reputation?
Agencies, in particular, are well positioned to push on these points. They sit between brands and technology providers, and they are the ones who will face the client when an automated recommendation goes wrong. Building a basic understanding of the data supply chain is not a technical indulgence. It is a form of due diligence, much like asking where a media partner’s inventory comes from.
The human premium
It is tempting to read the story of AI in advertising as one of steady disintermediation, with machines absorbing task after task until little remains for people. The data-labelling economy complicates that picture. Behind every system that appears to think for itself sits a layer of human interpretation that taught it what to notice, what to avoid and what a particular word means in a particular place.
For India, this is both a challenge and an opportunity. The same linguistic and cultural complexity that frustrates imported tools gives local talent and local vendors a real advantage, provided the ecosystem invests in quality, fair pay and sound training rather than racing to the cheapest price. Companies that treat annotation as a strategic capability, rather than a procurement line item, are likely to build better products and earn more durable trust.
The AI ad tools that succeed in India will not be those with the loudest launch or the largest model. They will be the ones that understand the country well enough to have been taught properly in the first place. And that education, for the foreseeable future, will keep depending on people.